🌟 If you find ggpicrust2 helpful, please consider giving us a star on GitHub! Your support greatly motivates us to improve and maintain this project. 🌟
ggpicrust2 analyzes PICRUSt2 predicted functional profiles with pathway aggregation, differential abundance analysis, gene-set testing, annotation, and visualization. It also summarizes taxon contributions and compares results across analysis methods. Method agreement is a sensitivity analysis on the same data; it does not validate measured pathway activity.

News
See release notes for release notes and fixes. The tutorials below cover DAA, camera/fry and preranked gene-set tests, and taxon contribution analysis.
Table of Contents
Citation
If you use ggpicrust2 in your research, please cite the following paper:
Chen Yang and others. (2023). ggpicrust2: an R package for PICRUSt2 predicted functional profile analysis and visualization. Bioinformatics, btad470. DOI link
The package citation is also available directly in R:
citation("ggpicrust2")Installation
You can install the development version of ggpicrust2 from GitHub with:
# install.packages("devtools")
devtools::install_github("cafferychen777/ggpicrust2")
Required dependencies are installed with the package. Optional analysis backends must be installed separately for the methods you use:
| Workflow | Optional packages used in the tutorial |
|---|---|
| LinDA and KEGG annotation |
MicrobiomeStat, KEGGREST
|
| ALDEx2 alternative | ALDEx2 |
| camera/fry GSEA | limma |
| Preranked GSEA and its displays |
fgsea, ggridges, ComplexHeatmap, circlize, igraph
|
| GSEA/DAA Venn plot | ggVennDiagram |
The general workflow and GSEA tutorial include installation commands for their examples. The full dependency declarations are in DESCRIPTION.
Project Links
Use the project resources below for stable updates and support:
- Package website: https://cafferychen777.github.io/ggpicrust2/
- Source repository: https://github.com/cafferychen777/ggpicrust2
- Issue tracker: https://github.com/cafferychen777/ggpicrust2/issues
- Release notes: release notes
Workflow
Start with the bundled data. No external example files are needed. Install MicrobiomeStat for LinDA and KEGGREST for online KEGG annotation as shown in Using ggpicrust2.
ggpicrust2()
library(ggpicrust2)
data("ko_abundance")
data("metadata")

results <- ggpicrust2(
  data = ko_abundance,
  metadata = metadata,
  group = "Environment",
  pathway = "KO",
  daa_method = "LinDA",
  ko_to_kegg = TRUE,
  x_lab = "pathway_name"
)
results[[1]]$plot
head(results[[1]]$results)
A plot can be NULL when there are no significant, annotated pathways. For your own PICRUSt2 files, replace data = ko_abundance with file = "your_abundance.tsv" and supply metadata with matching sample IDs.
Stepwise workflow
Using ggpicrust2 is the canonical complete walkthrough. It uses the same LinDA settings as the example above and covers sample alignment, annotation, plotting, ALDEx2 test selection, and contribution analysis. The GSEA tutorial covers gene-set tests, contrasts, covariates, and method-specific visualization.
Output
Each numbered result contains a method’s plot and annotated results table. The wrapper also returns aligned abundance, metadata, group, and daa_results_df for further analysis. These remain predictions from PICRUSt2; statistical differences do not establish measured pathway activity or causation.
function details
ko2kegg_abundance()
data("ko_abundance")
kegg_abundance <- ko2kegg_abundance(data = ko_abundance)
The default is the mean of the upper half of observed KO abundances in each pathway/sample, not a sum or a complete reconstruction of pathway activity. Overlapping pathways share KOs. method = "sum" is a different aggregation and changes the analysis scale. See ?ko2kegg_abundance for the mapping and prokaryote-filtering rules. A retained KEGG label is not proof of that pathway’s activity or organism specificity; shared KOs can map to several biological contexts.
pathway_daa()
data("metacyc_abundance")
data("metadata")
metacyc_matrix <- tibble::column_to_rownames(metacyc_abundance, "pathway")
metacyc_results <- pathway_daa(
  abundance = metacyc_matrix, metadata = metadata,
  group = "Environment", daa_method = "LinDA"
)
Features are rows and samples are columns. Choose a method for the input scale and design. Count-based methods may round non-integer predicted abundances; that is not an equivalent treatment of normalized or continuous data. For multiple groups, specify the reference and inspect the returned group pairs.
compare_daa_results()
This compares discoveries at an adjusted p-value threshold. ALDEx2 returns multiple tests; split its results by method before passing one table per test. The function treats each list element as one discovery set. Use ?compare_daa_results for a runnable example. Agreement is sensitivity analysis on the same data, not independent biological validation.
pathway_annotation()
annotated_metacyc <- pathway_annotation(
  pathway = "MetaCyc", daa_results_df = metacyc_results,
  ko_to_kegg = FALSE
)
Annotation adds labels without converting the abundance or changing the unit of a p-value. To test KEGG pathways, aggregate KO abundance before DAA. ko_to_kegg = TRUE then selects online KEGG annotation for those result rows; only rows below p_adjust_threshold are annotated. Local KO, EC, MetaCyc, and KEGG reference annotation is also available; see ?pathway_annotation.
pathway_errorbar()
Use the stepwise tutorial for a complete example. Group is a vector of labels, unlike group, which is a metadata column name. setNames(metadata$Environment, metadata$sample_name) preserves sample identity when the metadata and abundance table have different orders.
The abundance panel summarizes per-sample relative abundances using the full input feature matrix as the denominator. Use select to limit displayed rows; pre-filtering the abundance matrix changes the denominator. A supplied model log2_fold_change is preserved; otherwise the plot derives a descriptive ratio of group mean relative abundances. These are not necessarily the same quantity. See ?pathway_errorbar and ?pathway_errorbar_table.
pathway_heatmap()
sig_features <- unique(metacyc_results$feature[
  !is.na(metacyc_results$p_adjust) & metacyc_results$p_adjust < 0.05
])
if (length(sig_features) > 0) {
  pathway_heatmap(metacyc_matrix[sig_features, , drop = FALSE],
                  metadata, group = "Environment")
}
Keep stable feature IDs as row names; descriptions can be duplicated or missing. Colors are within-feature z-scores across samples. They do not compare absolute abundance between different pathways or establish statistical significance.
pathway_pca()
set.seed(123)
abundance_example <- matrix(rexp(30), nrow = 3, ncol = 10,
  dimnames = list(c("PathwayA", "PathwayB", "PathwayC"), paste0("Sample", 1:10)))
metadata_example <- data.frame(
  sample_name = colnames(abundance_example),
  group = factor(rep(c("Control", "Treatment"), each = 5))
)
pathway_pca(abundance_example, metadata_example, group = "group")
PCA centers and scales features. It does not normalize sample library sizes. This simulated example illustrates the display, not a biological group effect. Use preprocessing appropriate for the study; visible separation is not a test.
compare_metagenome_results()
Use this for matrices measuring the same samples, with shared sample IDs. It retains the pairing in DAA and reports median per-feature Spearman correlations with joint sample-label permutation p-values. See ?compare_metagenome_results for a self-contained example and the exact feature-intersection rules. Correlation is not proof of unbiased agreement.
taxa contribution workflow
The contribution tutorial includes synthetic inputs and examples for real PICRUSt2 files. read_contrib_file(), read_pathway_contrib_file(), and read_strat_file() standardize their formats; aggregate_taxa_contributions() sums contributions at the requested rank.
For KO-level contributions, KEGG pathway filters are expanded to their KO members. Output remains KO-level contributions; this operation does not infer pathway contributions. For pathway-level MetaCyc input, matching MetaCyc IDs are filtered directly. Use metadata and taxonomy from the same dataset.
pathway_gsea()
Use gene/enzyme-level abundance, not already aggregated pathways. The GSEA tutorial explains the input assumptions:
-
cameratests a competitive null with an inter-gene correlation adjustment. -
frytests a self-contained null; it is not an interchangeable faster camera. -
fgseaandclusterProfileruse a ranked feature list and a different null.
The camera/fry implementation uses voom on count-like abundance. A successful fit is not evidence that its uncertainty model is calibrated for every kind of predicted, normalized, or relative abundance.
visualize_gsea()
See the GSEA visualization examples. For camera/fry, the compatibility column NES contains a signed -log10(pvalue) score, not a normalized enrichment score or effect size. enrichment_plot is a score-summary bar chart, not a running enrichment curve.
Network edges and the GSEA heatmap require leading-edge genes from a preranked method. camera/fry do not supply these genes. A leading-edge heatmap displays row-standardized mean supplied abundance per leading-edge set, not one row per gene or measured gene expression.
compare_gsea_daa()
Compare matching pathway identifiers and compatible contrasts. The GSEA tutorial shows KEGG pathway DAA versus KEGG GSEA. Gene-set and pathway-abundance tests answer different questions, so neither agreement nor disagreement alone establishes that a method is correct.
gsea_pathway_annotation()
gsea_pathway_annotation() adds pathway names and classes. It preserves the method-specific scores and p-values; annotation cannot supply missing leading-edge genes or change the analysis level.
FAQ
Group length mismatch or incorrect group summaries
Group = "Environment" passes a single string, not the samples’ group labels. Use Group = setNames(metadata$Environment, metadata$sample_name) and replace those column names for your data. The sample names must cover all abundance columns. An unnamed vector is interpreted in abundance-column order; simply using metadata$Environment can silently mislabel samples when the two tables have different orders, including in the bundled example data.
The stepwise tutorial shows the complete workflow and checks. For errors constructing a plot, include sessionInfo() and the full error in an issue; loading additional plotting libraries does not resolve a group-length or sample-alignment error.
Plotting and KEGG connection errors
For plotting errors, report the full error and sessionInfo(). Loading extra plotting packages does not fix mismatched data, unsupported arguments, or incompatible dependency versions.
For KEGG HTTP errors, inspect the reported feature ID and confirm the annotation mode matches the identifier level. A bad request is not fixed by restarting R. For certificate failures, check the system clock, certificate configuration, and network access. Local reference annotation is available when live KEGG access is unnecessary.
More than 30 significant features clutter the plot
Use select to display a subset of significant feature IDs, or increase max_features deliberately. For the objects created by the stepwise tutorial:
significant_results <- annotated_daa[
  !is.na(annotated_daa$p_adjust) & annotated_daa$p_adjust < alpha, , drop = FALSE
]
top_features <- head(
  significant_results$feature[order(significant_results$p_adjust)], 20
)
if (length(top_features) > 0) {
  pathway_errorbar(
    abundance = kegg_pathway_abundance,
    daa_results_df = annotated_daa,
    Group = sample_groups,
    select = top_features,
    ko_to_kegg = TRUE,
    p_values_threshold = alpha,
    x_lab = "pathway_name"
  )
}
This only limits the display; it does not rerun testing, round p-values, or change the significance threshold. head() also works when fewer than 20 pathways are significant.
No statistically significant pathways
An empty set at the chosen adjusted p-value threshold is a valid result. Retain the results table and report the method, threshold, and sample size. Check input quality and model assumptions; do not relax thresholds, remove samples, or switch tests solely to obtain a plot. Prespecify the primary analysis and label sensitivity analyses separately.
Author’s Other Projects
- MicrobiomeStat: The MicrobiomeStat package is a dedicated R tool for exploring longitudinal microbiome data. It also accommodates multi-omics data and cross-sectional studies, valuing the collective efforts within the community. This tool aims to support researchers through their extensive biological inquiries over time, with a spirit of gratitude towards the community’s existing resources and a collaborative ethos for furthering microbiome research.
If you’re interested in helping to test and develop MicrobiomeStat, please contact cafferychen7850@gmail.com.
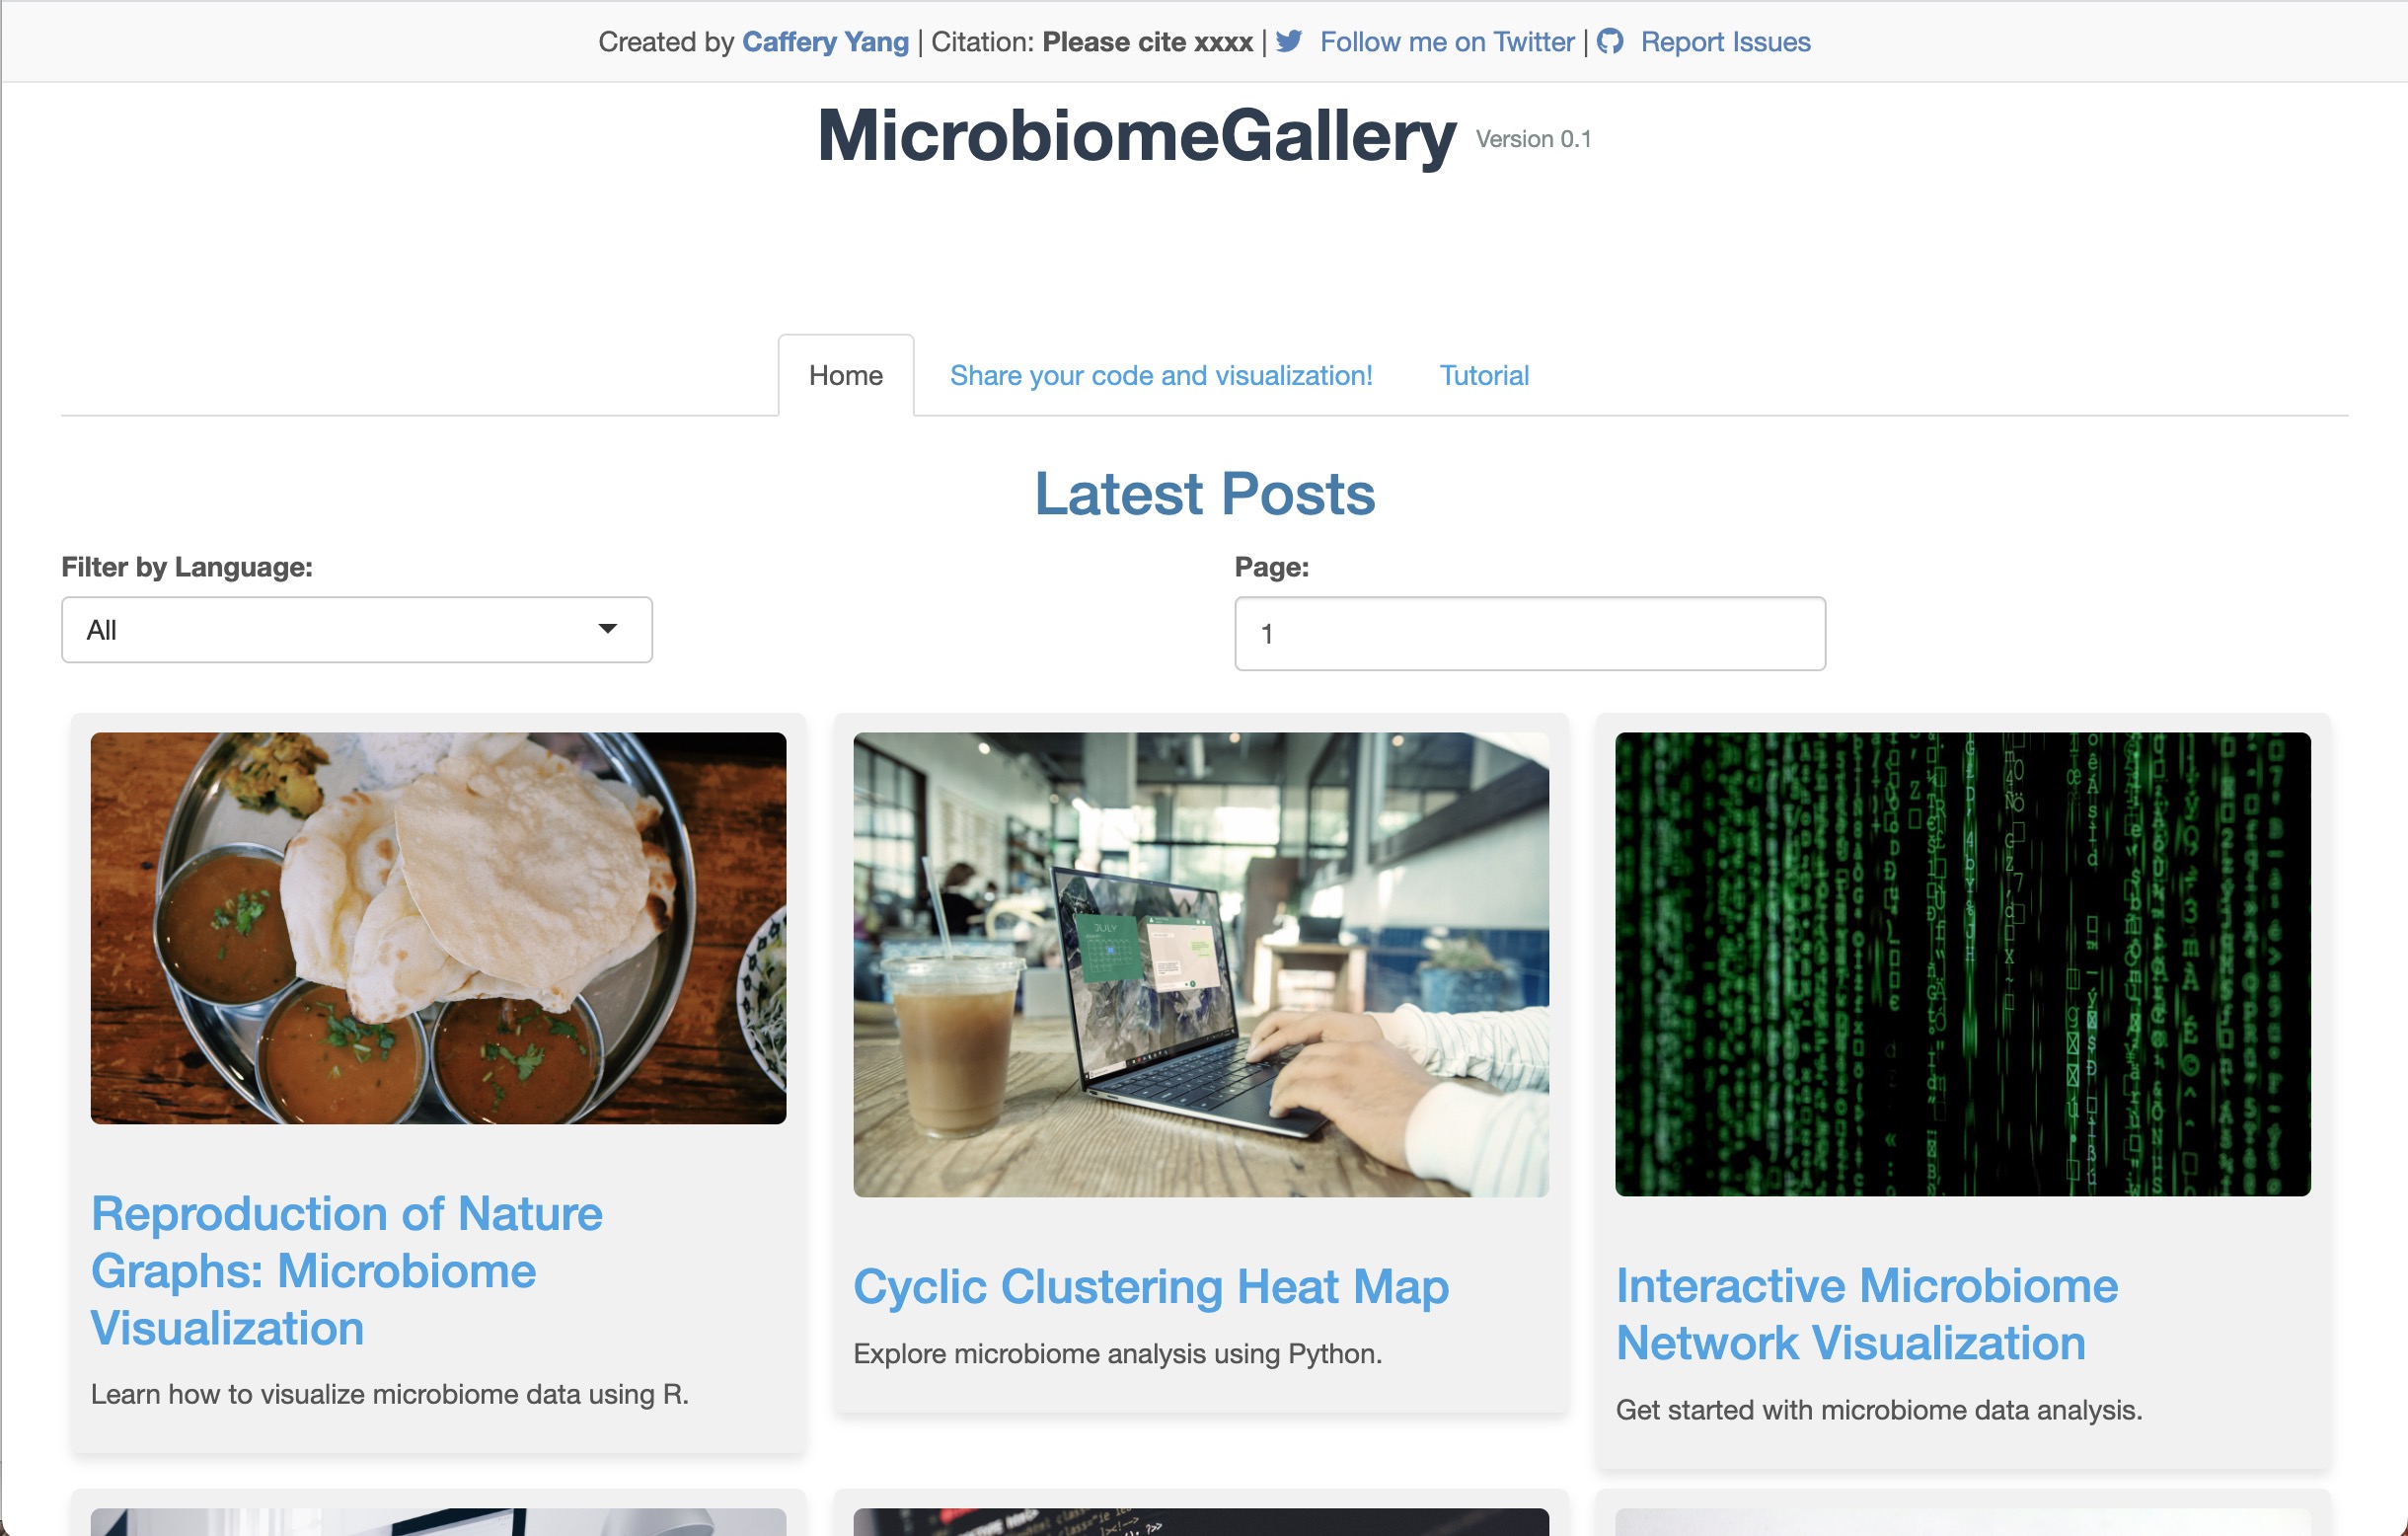
- MicrobiomeGallery: This is a web-based platform currently under development, which aims to provide a space for sharing microbiome data visualization code and datasets.
We look forward to sharing more updates as these projects progress.